TensorStack is an open-source C# SDK for running image, video, audio and language models on local GPUs — one typed, async API over ONNX Runtime, stable-diffusion.cpp and Hugging Face Diffusers.
Generate images and video, transcribe and synthesize speech, and run language models from the same C# codebase. Each capability ships as a focused NuGet package on a shared core.
// Upscale an image and a video 4x with ONNX Runtime
var pipeline = UpscalePipeline.Create(new UpscalerConfig
{
    ScaleFactor = 4,
    Normalization = Normalization.ZeroToOne,
    ExecutionProvider = Provider.GetProvider(),
    Path = @"Models\RealESR-General-4x.onnx"
});

// Image
var image = new ImageInput("Input.png");
var upscaled = await pipeline.RunAsync(
    new UpscaleImageOptions { Image = image });
await upscaled.SaveAsync("Output.png");

// Video, streamed frame by frame
var stream = await VideoInputStream.CreateAsync("Input.mp4");
var video = pipeline.RunAsync(
    new UpscaleStreamOptions { Stream = stream.GetAsync() });
await video.SaveAsync("Output.mp4");
// Text-to-image with a GGUF model via stable-diffusion.cpp
using var backend = new StableDiffusionBackend(VendorType.Nvidia);
await backend.InitializeAsync();

using var pipeline = new StableDiffusionPipeline(backend);
var device = pipeline.Devices
    .FirstOrDefault(x => x.Type == DeviceType.GPU);

await pipeline.LoadAsync(new StableDiffusionOptions
{
    Backend = device.Backend,
    LlmPath = "Qwen3VL-4B-Instruct-Q8_0.gguf",
    VaePath = "diffusion_pytorch_model.safetensors",
    DiffusionModelPath = "Krea-2-Turbo-Q8_0.gguf"
});

var options = pipeline.DefaultImageOptions with
{
    Prompt = "cute cat", Width = 1024, Height = 1024, Seed = 420
};
var result = await pipeline.GenerateImageAsync(options);
await result.SaveAsync("OutputImage.png");
// Drive a Hugging Face Diffusers pipeline from C#
using var backend = new HuggingFaceBackend(VendorType.Nvidia);
await backend.InitializeAsync(); // creates the Python environment

var config = new PipelineConfig
{
    Path = "Qwen/Qwen-Image-Edit",
    Pipeline = "QwenImagePipeline",
    ProcessType = ProcessType.ImageEdit,
    DataType = DataType.Bfloat16,
    MemoryMode = MemoryModeType.OffloadCPU
};

using var pipeline = new PythonPipeline(
    config, PipelineProgress.ConsoleCallback);
await pipeline.LoadAsync(); // downloads the model on first run

var response = await pipeline.GenerateAsync(new PipelineOptions
{
    Prompt = "Yarn art style",
    Steps = 30,
    GuidanceScale = 4f,
    ImageInput = new ImageInput("Image.png")
});
await response.AsImageTensor().SaveAsync("Result.png");
// Speech-to-text with Whisper on ONNX Runtime
var provider = Provider.GetProvider(0);
var pipeline = WhisperPipeline.Create(
    provider, @"Models\Whisper-Base", WhisperType.Base);

var result = await pipeline.RunAsync(new GenerateOptions
{
    Task = TaskType.Transcribe,
    Language = LanguageType.EN,
    AudioInput = await AudioInput.CreateAsync("speech.mp3")
});

Console.WriteLine(result.Result);
Why TensorStack
Built for AI that runs on your own hardware.
TensorStack gives .NET teams the building blocks for local inference — engines, GPU acceleration and typed pipelines — without leaving C#.
Private by design
Inference runs on the user's own GPU, so prompts, media and outputs stay on the device, with no per-request fees.
Three engines, one API
ONNX Runtime, stable-diffusion.cpp and Hugging Face Diffusers behind consistent, strongly typed C# pipelines.
Every major GPU
CUDA for NVIDIA, Vulkan across AMD, Intel and NVIDIA, and DirectML on any DirectX 12 GPU.
Modular packages
Focused NuGet packages on a shared core. Install only what you use, and extend it with your own providers.
Native .NET
C# from the UI down to the tensors, with Python interop through CSnakes only where the model ecosystem requires it.
Open source
Apache-2.0 licensed and developed in the open on GitHub. Inspect it, extend it and ship it without lock-in.
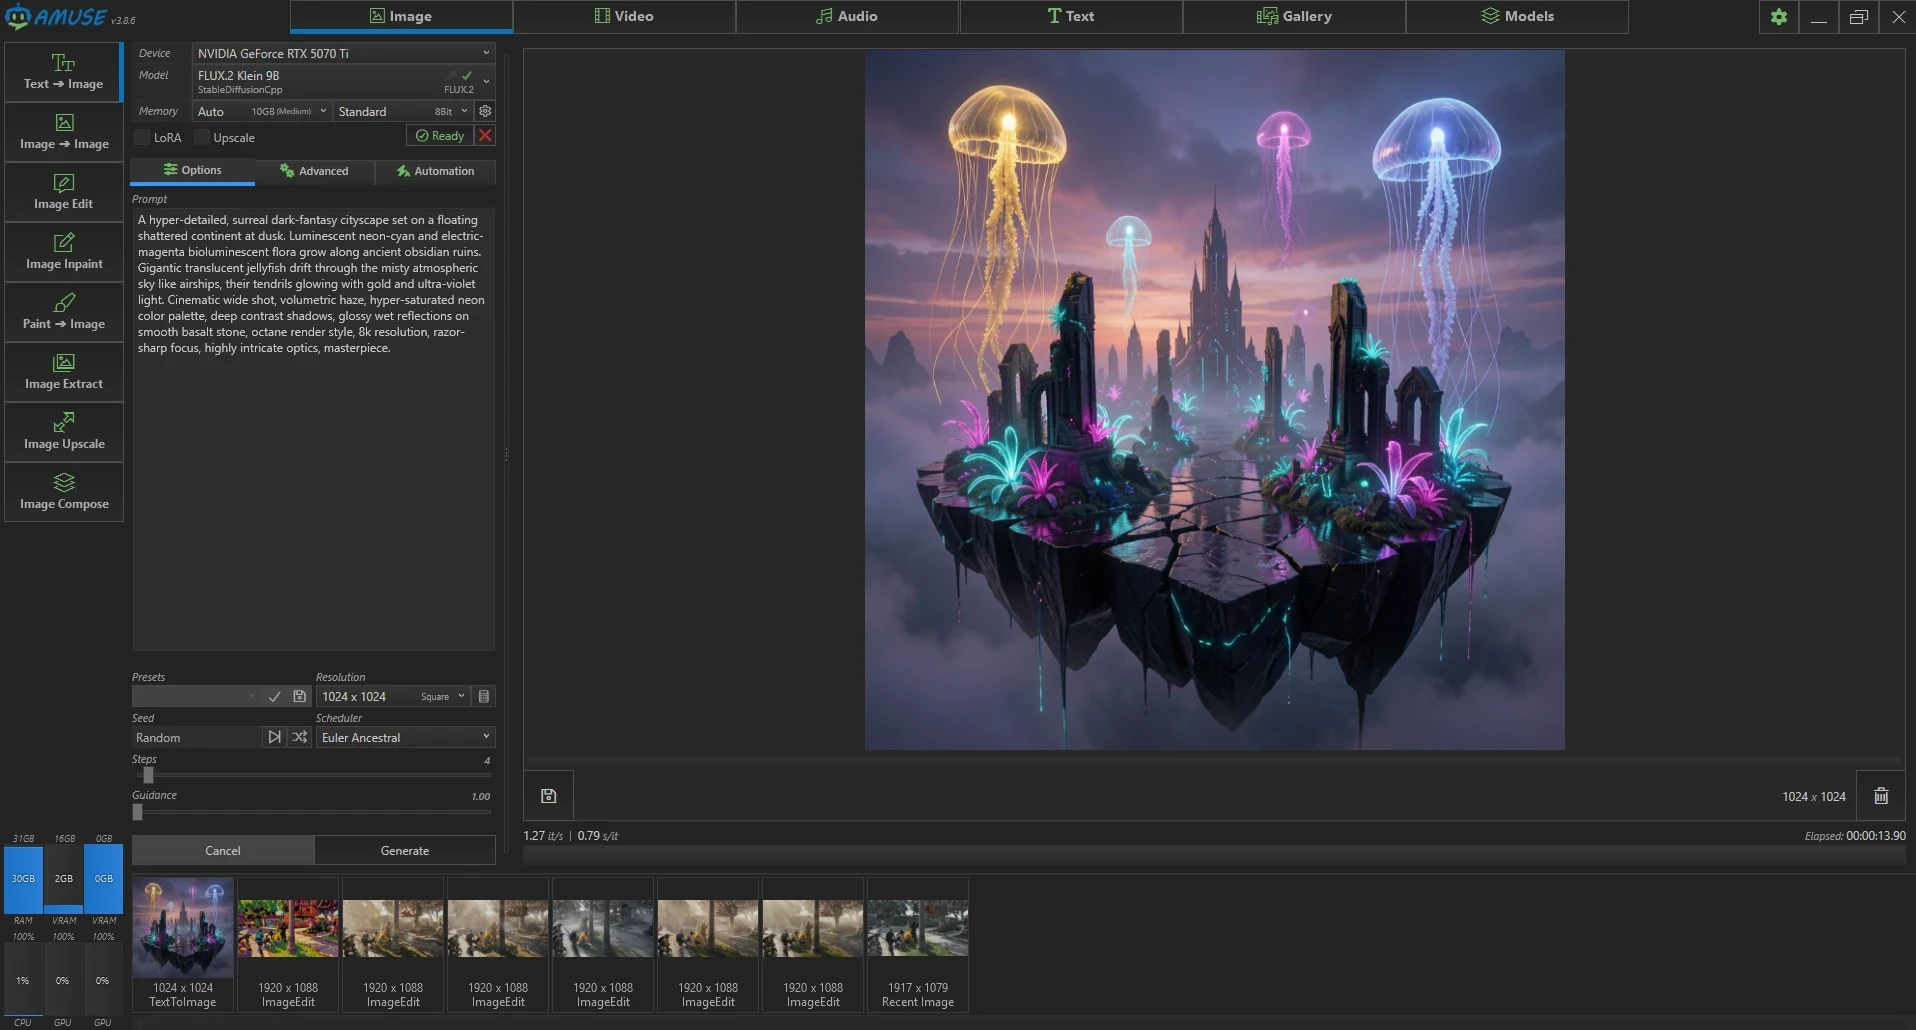
Reference application
Amuse, built on TensorStack.
A complete desktop AI studio for Windows and the reference application for the SDK: a working demonstration of what TensorStack can do, and an open-source blueprint for your own app.
40+ model pipelines across image, video, audio and text
All three engines — stable-diffusion.cpp, ONNX Runtime and Hugging Face — in one app
Apache-2.0 source you can read, learn from and build on
Amuse · Image studioFLUX.2 Klein 9B on stable-diffusion.cpp
Open source
Built in the open.
TensorStack and Amuse are developed on GitHub under the Apache-2.0 license. Star a repository, open an issue or send a pull request — contributions are welcome.

 Explore Amuse